Mistral Releases 1 Trillion-Parameter Le Chonk, Challenging China’s Lead in Open-Weight AI
Image: TechCrunch AI
Main Takeaway
Mistral released the weights for its 1 trillion-parameter Large 4 model, claiming top open-model performance in coding and cybersecurity while matching China’s GLM-5.3.
Jump to Key PointsSummary
Mistral’s open-weight challenge
Mistral has released the weights for Mistral Large 4, a 1 trillion-parameter model nicknamed “Le Chonk,” positioning the system as the leading Western open-weight model for coding agents and cybersecurity. The French company says the finalized release matches or edges China’s GLM-5.3 on key software-engineering tests, closing a gap that has made Chinese laboratories the dominant force in downloadable frontier models.
The release gives businesses, governments, and researchers the ability to download and deploy the model themselves. Mistral frames that control as especially valuable for cybersecurity, where organizations often need to keep sensitive data and defensive systems inside their own infrastructure. Closed providers such as OpenAI and Anthropic still lead on overall capability in the cited comparisons, but their models remain accessible primarily through APIs.
What Large 4 delivers
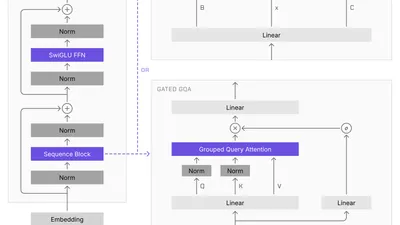
Large 4 combines a mixture-of-experts design with multimodal and multilingual capabilities. It accepts text and images, generates text, uses about 1 trillion total parameters with 49 billion active parameters, and supports a 1 million-token context window, according to its Hugging Face release documentation.
Mistral published FP8 and NVFP4 variants on Hugging Face, while third-party GGUF versions are available through Unsloth and the llama.cpp ecosystem. The model uses Mistral’s Ecosystem Open-Weight License, an MIT-derived license that places limits on model-as-a-service offerings. That licensing choice preserves broad deployment access while giving Mistral more control over commercial hosting than an unrestricted permissive license would provide.
Coding benchmarks drive the claim
The strongest performance claims center on agentic coding, where models must complete multi-step software tasks rather than answer isolated programming questions. Mistral says Large 4 narrowly leads the open models listed on Artificial Analysis’ Coding Agent Index and ties China’s GLM-5.3 on Terminal-Bench 4.0, a benchmark for coding agents.
Reinforcement-learning training on harder coding and cybersecurity problems raised Large 4’s Terminal-Bench 4.0 accuracy from 28% in the preview release to 41% in the finalized version, based on figures provided by Mistral. Fortune reported that Anthropic’s proprietary Mythos 5.1 scored 60.9% on the same benchmark, underscoring the difference between winning the open-weight category and leading the entire model market. The results establish a competitive milestone, while the comparison remains dependent on benchmark design and company-supplied figures.
Cybersecurity is the target market
Mistral is pitching Large 4 as a defensive tool for enterprises and governments facing more complex cyber threats. The company says training on increasingly difficult cybersecurity tasks improved the model’s ability to support automated defense, alongside its coding-agent performance.
Local deployment matters in this setting because security teams can control where prompts, source code, logs, and system information are processed. Open weights also allow organizations to inspect, adapt, and fine-tune the model for internal environments. Those advantages bring operational responsibilities: teams must supply computing capacity, manage updates, test model behavior, and set safeguards for systems that can assist with both defensive work and harmful cyber activity.
Why the release matters for AI sovereignty
Large 4 gives European institutions a prominent open-weight alternative as governments and companies debate dependence on American closed-model providers and Chinese downloadable systems. Mistral CEO Arthur Mensch described AI as “a tool for empowerment, not dominance,” while the company argues that open deployment can deliver advanced capability at a fraction of the compute and capital committed by closed laboratories.
The strategic contest is broader than a single leaderboard. Open weights let governments and companies run models under their own policies, but access still depends on hardware, engineering talent, electricity, and security expertise. A trillion-parameter model with 49 billion active parameters reduces some inference demands through its mixture-of-experts architecture, yet large-scale deployment remains a serious infrastructure project.
What happens next
The immediate test is adoption. Developers can now evaluate Large 4 directly, compare its coding and cyber capabilities with GLM-5.3, DeepSeek, Z.ai, and proprietary APIs, and determine whether its license fits their deployment plans. The availability of FP8, NVFP4, and community-created formats should widen the range of hardware and serving options.
Mistral’s announcement also raises the bar for open-weight rivals. Chinese labs retain strong positions in downloadable models, while OpenAI and Anthropic continue to lead some closed-model benchmarks. Large 4’s release therefore marks a shift in the competitive baseline: Western open-weight models now have a flagship contender, and the next contest will center on real-world reliability, operating cost, safety, and sustained performance rather than parameter count alone.
Key Points
Mistral released 1 trillion-parameter Large 4, challenging China’s lead in open-weight coding models.
Large 4 reached 41% on Terminal-Bench 4.0 after reinforcement learning on harder coding tasks.
The model supports multimodal input, multilingual use, mixture-of-experts inference, and a 1 million-token context.
Mistral targets cybersecurity teams seeking local control over sensitive data, systems, and model deployment.
Large 4 remains behind leading proprietary models on the cited coding benchmark, including Anthropic’s Mythos 5.1.
Questions Answered
Mistral Large 4 is a downloadable 1 trillion-parameter open-weight AI model from Mistral. It is a multimodal, multilingual mixture-of-experts system designed for coding agents, cybersecurity, and enterprise deployment.
Mistral says Large 4 matched or narrowly surpassed leading Chinese open-weight models on selected coding evaluations. The company reported a tie with GLM-5.3 on Terminal-Bench 4.0 and claimed a narrow lead on an agentic coding index.
Mistral Large 4 reached 41% accuracy on Terminal-Bench 4.0 in figures provided by Mistral. That result followed reinforcement-learning training on harder coding and cybersecurity tasks, though cited proprietary models still scored higher.
Mistral Large 4 is aimed at cybersecurity because local model deployment gives organizations more control over sensitive code, logs, prompts, and defensive systems. Mistral says the model was trained on increasingly difficult cyber problems to support automated defense.
Mistral Large 4 is available through Hugging Face in FP8 and NVFP4 variants. Community versions in GGUF format are also available from projects associated with Unsloth and llama.cpp.
Mistral Large 4 uses the Mistral Ecosystem Open-Weight License. The license is derived from MIT but includes limitations on offering the model as a service.
Source Reliability
50% of sources are highly trusted · Avg reliability: 81
Go deeper with Organic Intel
Simple AI systems for your life, work, and business. Each one includes copyable prompts, guides, and downloadable resources.
Explore Systems