NVIDIA Frames AI Factories Around Tokens per Watt, Grid Flexibility and Vera Rubin Infrastructure
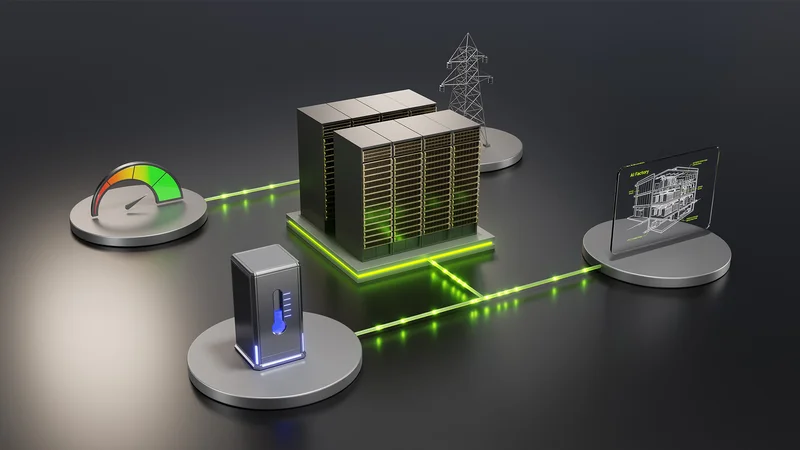
Image: NVIDIA Blog
Main Takeaway
NVIDIA is tying AI factory output to tokens per watt, combining Vera Rubin hardware, DSX software and grid-aware operations to raise computing efficiency.
Jump to Key PointsSummary
The metric shifts to tokens
NVIDIA is recasting AI infrastructure around tokens produced for each unit of power, making tokens per watt a central measure of factory productivity. The approach links model serving, training, cooling, networking and electricity management rather than treating the GPU as an isolated component.
That shift matters because AI facilities increasingly compete for scarce power as much as for chips. NVIDIA’s AI Infra Summit programming, technical posts and infrastructure partners all place energy efficiency beside performance and scale, establishing a production metric that connects data-center economics to the amount of useful model output delivered. The phrase “token factory” captures the intended operating model: electricity enters the facility, software and hardware transform it into inference or training work, and operators track the resulting token volume.
Vera Rubin supplies the hardware base
Vera Rubin is positioned as NVIDIA’s next major platform for increasing AI factory output while controlling power consumption. Summit coverage describes the platform alongside DSX advances, while industry analyses frame Vera Rubin as part of a broader transition toward integrated AI infrastructure rather than a standalone accelerator launch.
The platform discussion extends NVIDIA’s roadmap beyond individual GPUs to include compute, memory, networking, storage and facility design. Coverage from SiliconANGLE, StorageReview and Technology Magazine connects Vera Rubin with the company’s wider progression from Blackwell Ultra toward systems engineered for large-scale inference and training. The commercial goal is higher usable throughput per rack and per megawatt, which gives operators a clearer basis for comparing systems than peak accelerator specifications alone.
DSX reaches into the facility
NVIDIA’s DSX platform is designed to coordinate the AI factory across hardware, software and physical infrastructure. Datacenter Frontier’s coverage emphasizes DSX’s deeper role inside the data center, while NVIDIA’s technical material describes MaxLPS as a way to optimize performance per watt across changing workloads.
That system-level focus treats power, thermal conditions and workload scheduling as connected controls. An AI factory can adjust computing behavior as demand, cooling capacity or grid conditions change, instead of running every accelerator at a fixed level. Full-stack inference and training optimization also brings model execution, orchestration and infrastructure telemetry into the same efficiency calculation. The result is a production system tuned for sustained output, where a small reduction in idle capacity or cooling overhead can raise total tokens delivered without adding equivalent electrical supply.
Grid signals become operating inputs
AI factories are beginning to interact directly with electricity systems, as demonstrated by an Emerald AI facility responding to a signal from Silicon Valley Power during an evening demand spike. The event connected utility operations, data-center engineers and the AI infrastructure team in a live adjustment of power consumption.
That example points to a more flexible model for large computing sites. Facilities can vary workload intensity, shift tasks or change cooling and power settings when the grid is constrained, then restore output when conditions ease. NVIDIA’s focus on tokens per watt gives operators a way to measure the tradeoff: the relevant question is how much useful AI work remains available after a power adjustment. Grid responsiveness also gives utilities a practical mechanism for accommodating new AI load without treating every data center as an inflexible block of demand.
Economics move beyond chip speed
The business case for NVIDIA’s approach rests on output per megawatt, not simply faster chips. Higher token production from the same electrical capacity can improve the economics of cloud inference, enterprise model serving and large training clusters, while better coordination reduces the risk that expensive accelerators sit idle because of bottlenecks elsewhere.
NVIDIA’s summit messaging places this efficiency goal alongside a growing audience for infrastructure technology, with attendance reported at more than 8,000 people, up from 3,500 the previous year. That audience includes chip buyers, data-center operators, utilities and system builders, all of whom measure value differently. Hardware vendors care about system performance, operators care about utilization and power, and utilities care about predictable demand. A common token-based metric gives those groups a shared production language, although its usefulness still depends on workload, model size, response quality and latency targets.
What happens next for AI factories
NVIDIA is pushing AI factory design toward continuous optimization across the stack, with Vera Rubin supplying the compute platform and DSX coordinating workloads, power and facility behavior. The immediate next step is wider deployment of these systems in data centers where electricity availability and cooling capacity constrain expansion.
The approach will also test how comparable token-per-watt claims are across models and serving patterns. Training, batch inference and interactive applications place different demands on memory, networking and latency, so operators will need workload-specific measurements rather than a single universal score. Siemens’ operating-system framing and NVIDIA’s technical guidance both point toward tighter integration between industrial controls and AI infrastructure. If that integration delivers stable output under changing grid conditions, energy flexibility will become part of the factory’s production plan rather than an emergency response.
Key Points
NVIDIA is making tokens per watt a core measure of AI factory productivity.
Vera Rubin connects next-generation compute performance with higher output per rack and megawatt.
DSX coordinates workloads, cooling, power management and data-center infrastructure across the full stack.
Emerald AI demonstrated an AI facility adjusting consumption after a Silicon Valley Power grid signal.
NVIDIA’s strategy shifts infrastructure competition from peak chip speed toward sustained token production.
Questions Answered
NVIDIA uses tokens per watt to measure how much useful AI output a system produces for each unit of electricity. The metric connects model serving or training performance with power consumption, cooling and infrastructure utilization.
NVIDIA positions Vera Rubin as a platform for increasing AI throughput per rack and per megawatt. Its role extends across the broader factory architecture, including compute, memory, networking and facility efficiency.
NVIDIA DSX is an infrastructure platform for coordinating AI workloads with data-center power, thermal and operational conditions. Its MaxLPS and full-stack optimization work aims to raise performance per watt across inference and training.
NVIDIA’s Emerald AI example shows an AI facility adjusting power consumption after a Silicon Valley Power signal. Workload scheduling, computing intensity and cooling controls can help data centers reduce demand during grid stress.
Tokens per megawatt links AI capacity to the electricity required to produce it. Better output from existing power capacity can improve serving economics and help operators expand computing where new grid supply is limited.
Source Reliability
38% of sources are trusted · Avg reliability: 66
Go deeper with Organic Intel
Simple AI systems for your life, work, and business. Each one includes copyable prompts, guides, and downloadable resources.
Explore Systems